CSV to Markdown: Convert Tables Online or With Code
CSV to Markdown conversion turns comma-separated rows into a GitHub Flavored Markdown pipe table: a header row, a delimiter row, then your data. You can do it in a browser in seconds or script it in a dozen lines. This guide covers both and shows exactly where each method breaks.
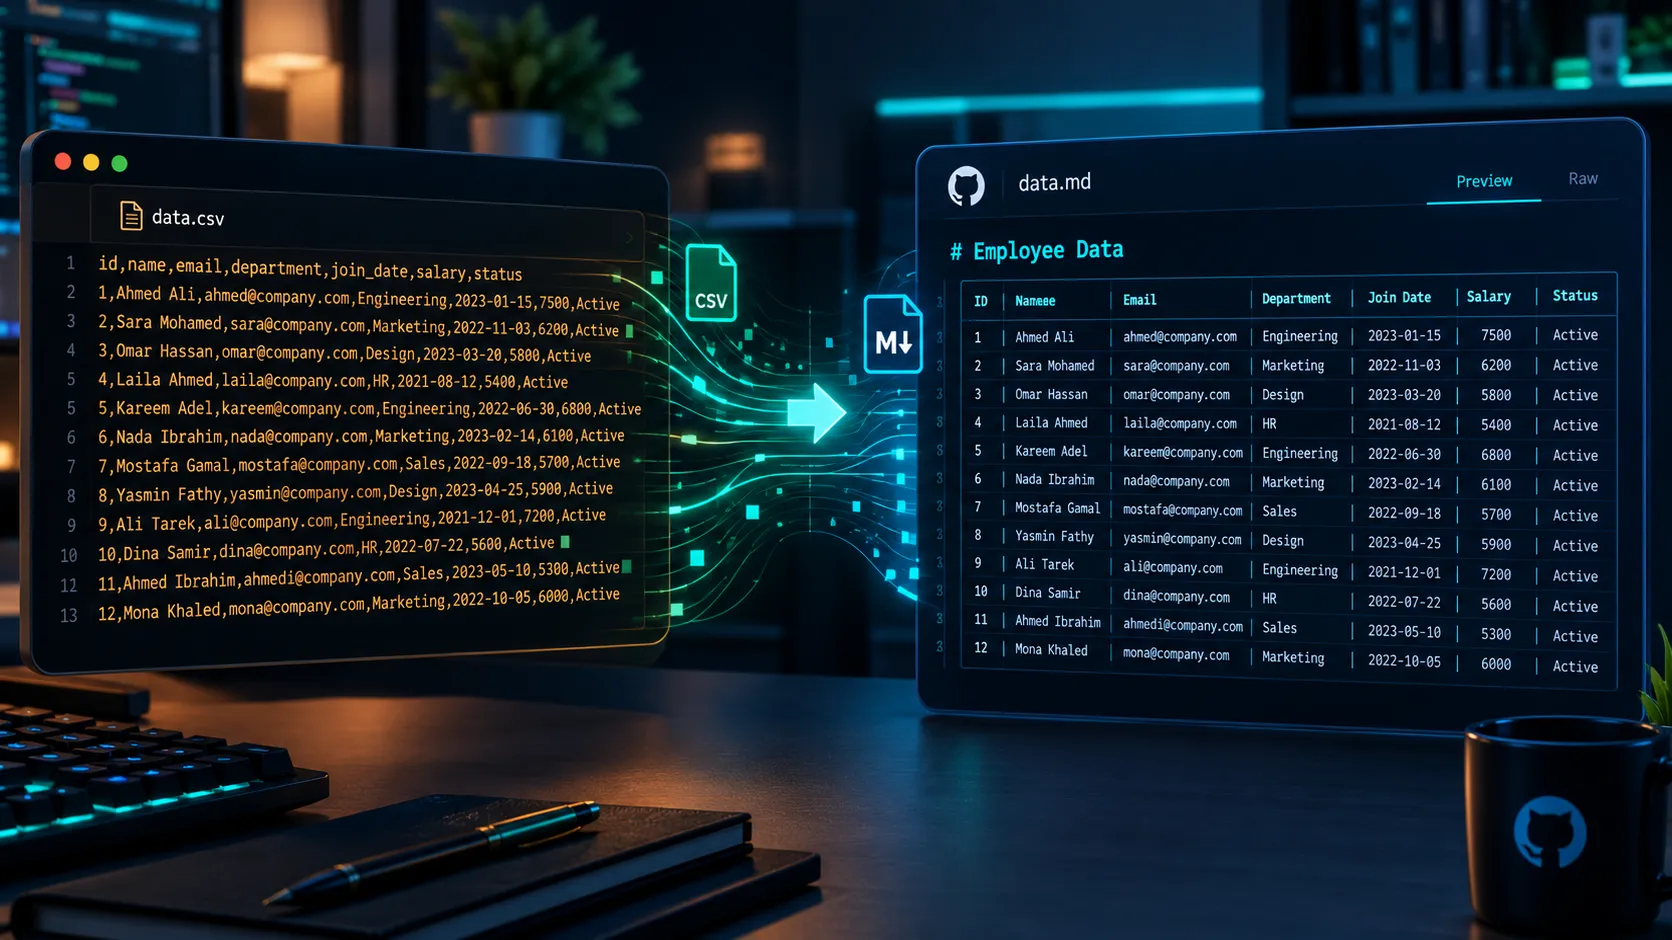
Raw CSV:
sku,product,warehouse,qty
0142,Standing Desk,"San Francisco, CA",18
0007,Cable Tray,"Austin, TX",240
Markdown pipe table:
| sku | product | warehouse | qty |
| --- | --- | --- | --- |
| 0142 | Standing Desk | San Francisco, CA | 18 |
| 0007 | Cable Tray | Austin, TX | 240 |
Need the result right now? Paste your data into the free CSV to Markdown converter. It runs in your browser, so there is nothing to install and no script to write.
Why Convert CSV to Markdown?
A CSV file is a download. A Markdown table is content. Once the data is a pipe table, it renders inline wherever Markdown renders:
- GitHub and GitLab: READMEs, issues, pull-request descriptions and wikis display the table in place. A linked CSV just sits there as a file.
- Obsidian and Notion: the table lands in your notes as native, searchable text rather than an attachment.
- Static site generators: Jekyll, Hugo and Astro turn pipe tables into HTML tables styled by your theme. Reference data such as config options, error codes or pricing tiers stays in one maintained CSV and gets regenerated into the docs.
- Version control: both formats put one row on one line, so a changed cell is a one-line diff. The Markdown table lives next to the prose it explains, so reviewers see the data change in context.
The cost is that Markdown tables have no types, no formulas and no merged cells. Keep the CSV as the source of truth and generate the Markdown from it.
Method 1: Free Online CSV to Markdown Converter
For one-off conversions, a browser tool beats writing code. Open the convert CSV to Markdown table online page and:
- Provide the data. Drop a
.csvor.tsvfile, or switch to the paste tab. - Set the three decisions CSV leaves open. Pick the delimiter (comma, semicolon, tab, pipe, or auto-detect), say whether row 1 is a header, and choose per-column alignment.
- Copy or download. The preview updates live. Copy the Markdown or save a
.mdfile.
What the converter does with the awkward cases:
- Quoted fields. It follows RFC 4180 quoting rules, so
"San Francisco, CA"stays one cell. - Pipes. Any
|inside a cell is escaped as\|, so a value cannot split a row. - Alignment. Choices are written into the delimiter row as
:---,:---:or---:, so right-aligned numeric columns survive a paste into GitHub or Obsidian. - Headerless files. With the header toggle off, it creates
Column 1,Column 2headings instead of consuming your first data row. - No type inference.
007stays007and1.10stays1.10.
It has limits. Multiline cells are collapsed to a single space, because a pipe table cell cannot hold a raw newline. Input must be UTF-8. If your export is Windows-1252 or UTF-16, re-save it as UTF-8 first.
Privacy. Conversion runs 100% client-side in the browser via JavaScript; files are never uploaded to a server. Site analytics are completely cookieless and aggregated. You can verify this yourself: open DevTools, switch to the Network tab, convert a file, and look for any request carrying your data. There won't be one.
The CSV page is one of 16 tools on the all-in-one Markdown conversion workspace (16 dedicated converters). The set includes an Excel to Markdown converter for workbooks, a TSV to Markdown converter for tab-separated data, JSON to Markdown for API output, and converters for HTML, YAML, XML, PDF and DOCX. If your source is a spreadsheet rather than a CSV export, read how to convert Excel to Markdown tables to see what a CSV export throws away.
Method 2: CSV to Markdown with Python and Node.js
Script the conversion when it runs on a schedule, in CI, or against hundreds of files.
Python with pandas
pip install pandas tabulate
import pandas as pd

df = pd.read_csv("inventory.csv", dtype=str, keep_default_na=False)
df = df.replace({r"\|": r"\\|", r"\r?\n": " "}, regex=True)
print(df.to_markdown(index=False, disable_numparse=True))
Each argument fixes a specific failure:
dtype=strstops pandas from turning0142into142.keep_default_na=Falsestops empty cells from becomingNaN.disable_numparse=Truestops the Markdown writer from rewriting12.50as12.5. Without it,dtype=stralone still loses trailing zeros on my test file.- The
replaceline escapes pipes and flattens newlines.to_markdown()does neither.
Input:
sku,product,price
007,Cable Tray,12.50
0142,Standing Desk,1249.90
00031,Monitor Arm,89.00
Output:
| sku | product | price |
|:------|:--------------|:--------|
| 007 | Cable Tray | 12.50 |
| 0142 | Standing Desk | 1249.90 |
| 00031 | Monitor Arm | 89.00 |
Python standard library (no dependencies)
import csv
import sys


def clean(value: str) -> str:
    return value.replace("|", r"\|").replace("\r\n", " ").replace("\n", " ")


def csv_to_markdown(path: str, delimiter: str = ",", encoding: str = "utf-8") -> str:
    with open(path, newline="", encoding=encoding) as f:
        header, *body = csv.reader(f, delimiter=delimiter)
    rows = [header, ["---"] * len(header), *body]
    return "\n".join("| " + " | ".join(clean(c) for c in r) + " |" for r in rows)


if __name__ == "__main__":
    print(csv_to_markdown(*sys.argv[1:]))
Run it with python csv2md.py inventory.csv. For a semicolon file, run python csv2md.py preise.csv ";". For a Windows-1252 export, run python csv2md.py export.csv "," cp1252. The csv module handles quoting and embedded newlines. The script never infers types, so leading zeros survive.
Node.js with PapaParse
npm install papaparse
Save as csv2md.mjs:
import fs from "node:fs";
import Papa from "papaparse";

const text = fs.readFileSync(process.argv[2], "utf8");
const { data } = Papa.parse(text.trim(), { skipEmptyLines: true });

const cell = (v) => String(v).replace(/\|/g, "\\|").replace(/\r?\n/g, " ");
const row = (r) => `| ${r.map(cell).join(" | ")} |`;

const [head, ...body] = data;
console.log([row(head), row(head.map(() => "---")), ...body.map(row)].join("\n"));
Run node csv2md.mjs orders.csv. A file with SO-20417,Status | Code,Pending | 402 produces | SO-20417 | Status \| Code | Pending \| 402 |. PapaParse can auto-detect delimiters, but for files you care about, pass delimiter explicitly.
Method 3: Terminal and VS Code
VS Code. Search the Marketplace for "csv to markdown table". Extensions such as CSV to Markdown Table by phoihos convert a selection in place. Run the quoted-comma and pipe fixtures from the matrix below through any extension before you trust it.
AWK. For clean, comma-only data with no quoting, this one-liner works:
awk -F, 'BEGIN{OFS=" | "} {$1=$1; print "| " $0 " |"} NR==1{s="|"; for(i=1;i<=NF;i++) s=s" --- |"; print s}' inventory.csv
Now feed it the CSV from the top of this article:
sku,product,warehouse,qty
0142,Standing Desk,"San Francisco, CA",18
Actual output:
| sku | product | warehouse | qty |
| --- | --- | --- | --- |
| 0142 | Standing Desk | "San Francisco | CA" | 18 |
The header has four columns and the data row has five. AWK splits on every comma and knows nothing about quotes, so the quoted address splits into two cells and keeps its stray quotation marks. Rows with a multiline cell break the same way, because AWK treats every physical line as a record. That is the reason to use a real CSV parser (PapaParse, Python's csv module, or the browser tool above) for anything exported from a database, a CRM or a spreadsheet.
How to Read a CSV File in R Markdown
This is the R Markdown answer to "how to read csv file in r markdown" and "how to import a csv file into r markdown". Put the file next to your .Rmd (or in a data/ folder), read it in a chunk, and print it with knitr::kable():
```{r load-inventory, echo=FALSE}
inventory <- read.csv("data/inventory.csv", colClasses = c(sku = "character"))
knitr::kable(inventory, align = c("l", "l", "l", "r"))
```
With the tidyverse:
```{r load-readr, echo=FALSE}
inventory <- readr::read_csv(
  "data/inventory.csv",
  col_types = readr::cols(sku = readr::col_character()),
  show_col_types = FALSE
)
knitr::kable(inventory)
```
Three details matter:
colClasses/col_types. R guesses types on read, so0142becomes142unless you declareskuas character.echo=FALSE. The chunk header{r, echo=FALSE}hides the code in the rendered document but still shows the table. Leave it off while debugging.- Working directory. Knitting evaluates chunks in the folder containing the
.Rmdfile, so"data/inventory.csv"is relative to the document, not to your console'sgetwd(). A script that works in the console can fail on Knit for this reason. If it does, rungetwd()inside a chunk, or build the path withhere::here("data", "inventory.csv").
For semicolon-delimited European files, use read.csv2() or readr::read_csv2(), which also treat the comma as the decimal mark.
To get a Markdown table out of R (for a README, say), run knitr::kable(inventory, format = "pipe") and paste the printed result.
Markdown to CSV: Reverse the Conversion
Pulling data back out of a README or wiki is a parsing job. The script below needs only the Python standard library. It finds every pipe table in a Markdown file, drops the delimiter row (including :---: alignment markers), splits on unescaped pipes only, converts \| back to |, and writes one properly quoted CSV per table.
#!/usr/bin/env python3
"""Extract GFM pipe tables from a Markdown file and write them as CSV.

Usage: python md2csv.py input.md [output_prefix]
One CSV per table: <prefix>_1.csv, <prefix>_2.csv ...
"""
import csv
import re
import sys
from pathlib import Path

# Delimiter row: cells made of dashes with optional alignment colons.
DELIM_ROW = re.compile(r"^\s*\|?\s*:?-{1,}:?\s*(\|\s*:?-{1,}:?\s*)*\|?\s*$")
# Split on a pipe that is NOT preceded by a backslash.
UNESCAPED_PIPE = re.compile(r"(?<!\\)\|")


def split_row(line: str) -> list[str]:
    line = line.strip()
    if line.startswith("|"):
        line = line[1:]
    if line.endswith("|") and not line.endswith("\\|"):
        line = line[:-1]
    cells = UNESCAPED_PIPE.split(line)
    return [c.strip().replace("\\|", "|") for c in cells]


def extract_tables(text: str) -> list[list[list[str]]]:
    lines = text.splitlines()
    tables, i = [], 0
    while i < len(lines) - 1:
        header, sep = lines[i], lines[i + 1]
        if "|" in header and "|" in sep and DELIM_ROW.match(sep):
            rows = [split_row(header)]
            i += 2
            while i < len(lines) and "|" in lines[i] and lines[i].strip():
                rows.append(split_row(lines[i]))
                i += 1
            width = len(rows[0])
            rows = [(r + [""] * width)[:width] for r in rows]  # pad or trim ragged rows
            tables.append(rows)
        else:
            i += 1
    return tables


def main() -> None:
    if len(sys.argv) < 2:
        sys.exit("usage: md2csv.py input.md [output_prefix]")
    src = Path(sys.argv[1])
    prefix = sys.argv[2] if len(sys.argv) > 2 else src.stem
    tables = extract_tables(src.read_text(encoding="utf-8"))
    if not tables:
        sys.exit("no pipe tables found")
    for n, rows in enumerate(tables, 1):
        out = Path(f"{prefix}_{n}.csv")
        with out.open("w", newline="", encoding="utf-8") as f:
            csv.writer(f).writerows(rows)
        print(f"wrote {out} ({len(rows) - 1} data rows)")


if __name__ == "__main__":
    main()
Given this Markdown:
| order_id | state | note |
| --- | --- | --- |
| SO-20417 | Status \| Code | Pending \| 402 |
| SO-20418 | Shipped | Say "hi" |
it writes:
order_id,state,note
SO-20417,Status | Code,Pending | 402
SO-20418,Shipped,"Say ""hi"""
How it works:
- Table detection. A table starts where a line containing a pipe is followed by a valid delimiter row. This ignores prose that happens to contain a
|. - Escaped pipes. The lookbehind
(?<!\\)\|splits only on structural pipes. Afterward,\|is converted back to a literal|. - Quoting.
csv.writerquotes any cell containing a comma, quote or newline, so the output opens correctly in Excel, Sheets or pandas. - Ragged rows. Short rows are padded and long ones are trimmed to the header width.
I round-tripped the pipe, quoted-comma and leading-zero fixtures from the matrix below through csv2md.py and then md2csv.py. The CSV that came out matched the original byte for byte. What does not survive: alignment markers (CSV has none), and the line breaks that were collapsed when the Markdown was written.
Fix Common CSV to Markdown Edge Cases
Most conversion bugs come from six inputs. I built one small fixture per hazard and ran five methods against them.
Test setup: Python 3.12.3 with pandas 3.0.2 and tabulate 0.10.0; Node 22 with PapaParse 5.7.0; mawk 1.3.4. The Python standard library script and the Node script are the ones printed above. The md-convert.org column follows the converter's documented behavior on its CSV page.
The six fixtures:
- Quoted comma:
0142,Standing Desk,"San Francisco, CA",18 - Pipes:
SO-20417,Status | Code,Pending | 402 - Multiline cell:
TK-5521,Label printer jams,"Jams on roll change./Replace the platen roller./Retest." - Semicolon file:
0142;Stehpult;1.249,90;18 - Leading zeros:
007,0142,00031 - Windows-1252 bytes:
0142,Müller GmbH,Zürich
Edge-Case Test Matrix
✅ = correct output. ⚠️ = correct only after the stated setting. ❌ = wrong output.
| Hazard | md-convert.org | pandas | Python stdlib | Node.js (PapaParse) | AWK |
|---|---|---|---|---|---|
| 1. Quoted commas | ✅ | ✅ | ✅ | ✅ | ❌ Splits "San Francisco and CA" into two cells |
| 2. Pipes in cells | ✅ Escapes as ` | ` | ❌ Unescaped pipes add extra cells; needs the replace line |
✅ Script escapes | ✅ Script escapes |
| 3. Multiline cell | ✅ Collapsed to a space | ❌ One record becomes three table rows; needs the replace line |
✅ Collapsed to a space | ✅ Collapsed to a space | ❌ Record split across three lines |
| 4. Semicolon file | ⚠️ Select ; (auto-detect can misfire) |
⚠️ Needs sep=";"; default gives one garbage column |
⚠️ Needs delimiter=";"; default splits 1.249,90 at the comma |
⚠️ Needs delimiter: ";" |
⚠️ Needs -F';' |
| 5. Leading zeros | ✅ No type inference | ⚠️ Needs dtype=str; add disable_numparse=True or 12.50 becomes 12.5 |
✅ | ✅ | ✅ |
| 6. Non-UTF-8 encoding | ❌ UTF-8 only; re-save first | ⚠️ Raises UnicodeDecodeError until you set encoding="cp1252" |
⚠️ Raises UnicodeDecodeError until you set encoding="cp1252" |
❌ Silent corruption: Mï؟½ller, Zï؟½rich |
❌ Passes raw bytes through; the output file is not valid UTF-8 |
What the matrix shows
- AWK fails three of six. Anything with quotes or embedded newlines needs a real parser.
- pandas needs four settings (
dtype,keep_default_na,disable_numparse, and the escapingreplace) before it passes the same fixtures. Its defaults are fine for numeric data and risky for identifiers. - Encoding is the dangerous one. pandas and Python fail loudly, which is good. Node's default UTF-8 read substitutes replacement characters with no error, so the mistake can reach your docs unnoticed.
- The standard library script passes once delimiter and encoding are set. It does so because it escapes pipes and flattens newlines itself, and never infers types.
Fixes for each hazard
- Encoding. Convert before parsing:
iconv -f cp1252 -t utf-8 export.csv > export-utf8.csv. In Excel, choose "CSV UTF-8" when saving. - Delimiters. If a file has
1.249,90-style numbers, assume semicolons and set the delimiter explicitly instead of trusting auto-detection. - Multiline text. If the line breaks matter, replace the newline with
<br>instead of a space in thecleanfunction. Most Markdown renderers, including GitHub, display<br>inside a table cell. - Pipes. Escape every
|as\|in cell values. GFM requires it even inside inline code in a table.
Frequently Asked Questions
What is the easiest way to convert a CSV to a Markdown table online for free?
Paste the data or drop the file into a browser-based converter such as the free CSV to Markdown converter on md-convert.org. Set the delimiter and header options, then copy the pipe table. Nothing is installed, no account is needed, and the file is never uploaded.
Can I convert Markdown tables back into CSV or Excel?
Yes. Run the md2csv.py script above to write each pipe table as a CSV file. Open that CSV in Excel or Google Sheets, or save it as .xlsx from there. The script converts escaped pipes (\|) back to | and drops the alignment row. Cell formatting and the original line breaks are not recovered.
How do I import and format a CSV inside R Markdown?
Read the file in a chunk with read.csv() or readr::read_csv(), declare ID columns as character to keep leading zeros, and print with knitr::kable(). Use {r, echo=FALSE} to hide the code. Paths resolve relative to the .Rmd file when you knit.
Is my data safe when using the online converter on md-convert.org?
Conversion runs 100% client-side in the browser via JavaScript; files are never uploaded to a server. Site analytics are completely cookieless and aggregated. To check, open your browser's DevTools Network tab, run a conversion, and confirm that no request carries your file.