How to Convert Excel to Markdown Tables Correctly
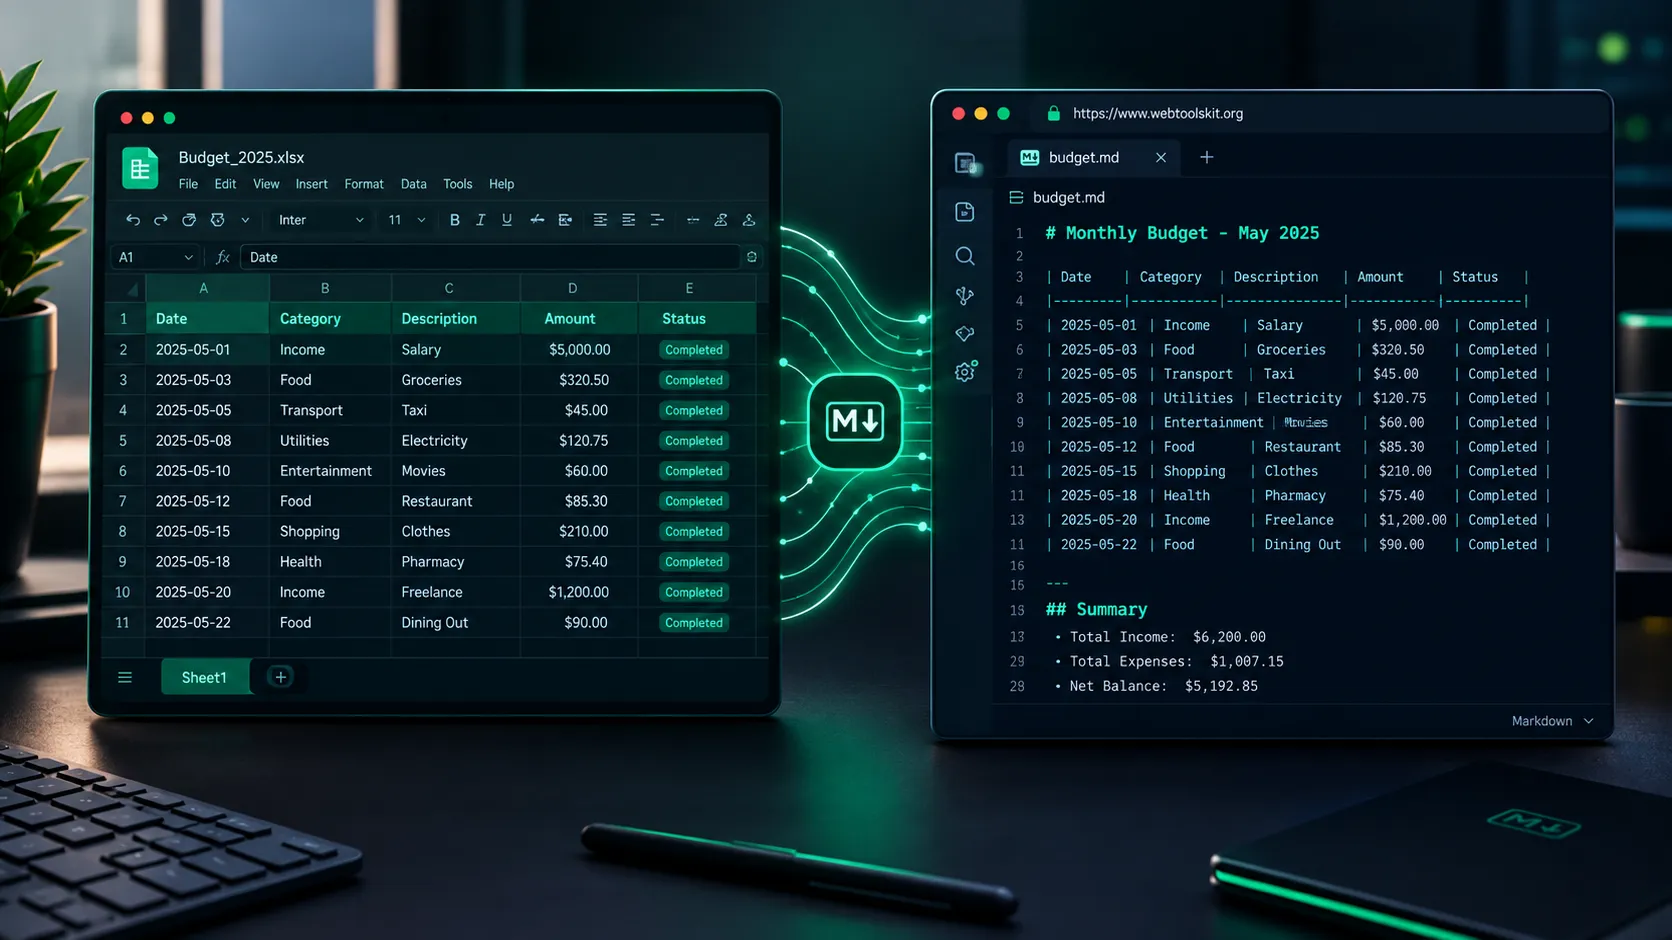
1. The Real Cost of Converting Spreadsheets in Modern Workflows
Spreadsheets still run the enterprise. Roadmaps, pricing matrices, and quarterly numbers all start life in a grid. But the moment that data needs to live in Git, a documentation site built on VitePress, Docusaurus, or MkDocs, or the context window of an LLM doing retrieval-augmented generation, a .xlsx file stops being useful. None of those systems read binary spreadsheets. They read Markdown.
So teams reach for whatever converts Excel to Markdown fastest, and that's where the trouble starts. A quick script strips the sheet name and drops four of the five tabs. A pasted table shows up in a pull request with every pipe character unescaped, breaking the render. Dates that read 2026-08-31 in Excel come out as 46265 in the Markdown, because the script read the raw cell value instead of the formatted one.
The worse version of this problem isn't cosmetic. It's the analyst who needs a quick excel to markdown table for a Confluence page and pastes an unreleased financial model into a random web converter to get it, with no idea where that file goes afterward, how long it's retained, or who else can see the upload log. For salary data, client lists, or anything under a data-processing agreement, that single upload is the whole risk.
This guide covers both problems: the mechanical one (why plain-text conversion breaks Excel tables) and the trust one (how to do this without a byte leaving your machine). The tool referenced throughout is a local Excel to Markdown converter that runs the entire process, unzip, parse, format, in a browser tab.
2. The Mechanics: Understanding Why Excel Tables Break in Plain Text
To understand why naive conversion fails, it helps to know what an .xlsx file actually is. It isn't a table in the way a CSV is a table. It's a ZIP archive, defined by the ECMA-376 / ISO/IEC 29500 standard (Office Open XML), containing a small filesystem of XML documents: xl/workbook.xml for the sheet index, one xl/worksheets/sheetN.xml per tab, xl/sharedStrings.xml holding every unique text value in the file, and xl/styles.xml holding number formats. A single cell reference like B7 is an XML element carrying a raw value and, separately, a style index pointing into that format table.
That separation is where the most common conversion bug lives. Excel does not store 2026-08-31 as a date string. It stores the integer 46265, the count of days since the 1900 epoch, and records elsewhere that this particular cell should be displayed as a date. A script that reads the raw <v> value and ignores the style table will faithfully output 46265 into your excel to markdown table, and it will look plausible enough that nobody catches it until a report is already wrong. Converting correctly means resolving the style index for every date and percentage column before a single row gets written.
Legacy .xls files complicate this further. They aren't XML at all — they're BIFF8, a compound binary format with its own record stream, a completely different animal from OpenXML. A converter that only understands .xlsx will simply fail on a decade-old .xls export from an ERP system. Modern parsing libraries like SheetJS read both formats and normalize them into one internal workbook model, so a spreadsheet saved in Excel 97 and one saved yesterday go through identical logic on the way to Markdown.
3. Step-by-Step: How to Convert Excel to Markdown Tables in Seconds
The actual conversion, done right, is three steps:
- Input. Drop the
.xlsxor.xlsfile onto the page, or click to browse. This uses the standard HTML5 File API — no plugin, no install. - Process. The file is read into an ArrayBuffer and handed to a parsing library (SheetJS) running inside a Web Worker, a background thread isolated from the page's main UI. It unzips the archive, resolves shared strings and style indexes, and builds a clean in-memory table.
- Output. The result is written as GFM (GitHub Flavored Markdown) pipe tables, with pipes escaped, alignment rows computed per column, and the whole thing copied to your clipboard or downloaded as a
.mdfile.
Try it now: if you have a spreadsheet on hand, open this browser-based Excel to Markdown tool and drag it in. Nothing uploads — you can confirm that yourself in the next section — and the output appears in under a second for anything short of a genuinely enormous workbook.
4. Edge Cases That Break Most Converters (And How to Handle Them)
Most tools that claim to convert Excel to Markdown fall apart on the same handful of edge cases.
Merged cells. GFM tables have no concept of colspan or rowspan — Markdown simply cannot represent a cell that spans multiple columns or rows. The standard, and only sane, convention is to keep the value in the top-left cell of the merged range and leave every other cell in that range empty. Anything else invents structure Markdown doesn't support.
Formulas versus cached results. Excel stores two things for a formula cell: the formula text (=SUM(B2:B40)) and the last value it calculated, cached in the file itself. A correct converter has no calculation engine and doesn't need one — it exports the cached result, which is the number that was on screen when the file was saved. The failure case is narrow: files generated by a library rather than by Excel sometimes ship a formula with no cached value, because the producer expected Excel to calculate it on open. Those specific cells export blank. The fix is simple — open the file in Excel or LibreOffice and save it once, which populates the cache.
Line breaks and pipe characters. A literal | inside a cell will terminate that table cell early and shift every column after it, which is the single most common way a converted table ends up visibly broken. It has to be escaped as \|. Hard line breaks inside a cell (common when Excel text wraps) need to collapse to spaces, since GFM table cells cannot contain a literal newline.
Multi-sheet workbooks. A five-tab workbook shouldn't silently become a one-tab Markdown file. The correct behavior is one ## Sheet Name section per worksheet, in workbook order, so nothing gets dropped and nothing needs a picker that can default to the wrong tab.
5. Concrete Visual Walkthrough: Before and After Conversion
Here's a representative "Q3_Pipeline" sheet, with a mix of dates, currency, percentages, and a negative value in accounting-style parentheses:
Input (spreadsheet):
Sheet "Q3_Pipeline":

Region | Signed      | Revenue   | Growth
EMEA   | 2026-08-31  | 1,234.50  | 12.5%
APAC   | 2026-09-01  | (98.25)   | 40.0%

(Revenue is =SUM(...) with a cached result;
 Signed cells are real dates, format yyyy-mm-dd)
Output (GFM Markdown):
## Q3_Pipeline

| Region | Signed | Revenue | Growth |
| --- | --- | ---: | ---: |
| EMEA | 2026-08-31 | 1,234.50 | 12.5% |
| APAC | 2026-09-01 | (98.25) | 40.0% |
Notice three things happened automatically: the sheet name became an ## heading, the two numeric columns (currency and percentage) picked up right-alignment (---:) while the date and text columns stayed left-aligned, and the parenthesized negative was recognized as numeric rather than as stray text. That alignment logic is inferred by inspecting every non-empty cell in a column — if all of them are numeric (including currency symbols, thousands separators, and accounting negatives), the column right-aligns. Date columns are deliberately excluded from that rule, since a right-aligned date reads worse than a left-aligned one.
6. Architectural Breakdown: 100% Client-Side Privacy Explained
The privacy claim behind a genuinely local excel to markdown workflow isn't a policy promise — it's an architectural fact you can verify yourself. When a file is dropped onto the page, it's read into an ArrayBuffer using the browser's FileReader API and handed off to a Web Worker, a background JS thread that does the parsing without blocking the interface. Everything from there, unzipping the archive, resolving XML, computing alignment, happens on your own CPU. There is no fetch() call, no XMLHttpRequest, and no multipart/form-data POST anywhere in that chain, because there's no server endpoint designed to receive the file.
You can verify this yourself: open Chrome DevTools, switch to the Network tab, and drop a spreadsheet onto the converter. Watch the request log while it processes. For a properly built local converter, you'll see nothing carrying your file — no upload initiates, because none is coded to exist.
That distinction matters more for spreadsheets than almost any other file type, because spreadsheets are where salaries, unreleased financials, client contact lists, and clinical trial data live. A server-based converter that accepts your workbook has, at minimum, created a copy of it somewhere you now have to reason about: retention windows, subprocessor agreements, data residency, breach notification obligations. For teams operating under GDPR, HIPAA, or SOC 2 commitments, "we didn't upload it" is a materially simpler compliance story than "we uploaded it and deleted it afterward, we promise." This same browser-first architecture is what makes sense to apply consistently — it's the same reasoning that extends across an entire client-side document conversion suite handling Word DOCX, PDF, CSV, and HTML alongside Excel.
7. Alternative Conversion Methods & When to Use Them
A local converter isn't the only path from Excel to Markdown, and it isn't always the right one. Here's an honest comparison:
| Method | Best For | Setup | Multi-Sheet Handling | Privacy |
|---|---|---|---|---|
| Browser converter | Ad hoc tasks, confidential data | None | Automatic | 100% local |
| Python (pandas) | Scheduled/batch ETL pipelines | Python + packages | Manual loop per sheet | Depends on where it runs |
| Pandoc + CSV | Existing Pandoc pipelines | Toolchain install | Breaks (one sheet per export) | Depends on where it runs |
| Manual copy-paste | A single, tiny table | None | N/A | Fully local |
Python (pandas / openpyxl / tabulate) is the right call when this needs to run unattended, as part of a CI job or a nightly ETL script:
python
import pandas as pd

df = pd.read_excel("report.xlsx", sheet_name="Q3_Pipeline")
print(df.to_markdown(index=False))
It's reliable for automation, but read_excel inherits the same date-serial trap discussed earlier unless you explicitly handle formatting, and you're responsible for looping over every sheet yourself.
Pandoc, despite being the standard tool for document format conversion, doesn't read .xlsx natively at all. Any Pandoc-based workflow has to export to CSV first, which reintroduces every CSV problem: commas inside text fields break naive parsing, quoted multi-line cells are easy to mishandle, multi-sheet workbooks collapse to one file per sheet, and date formatting is lost entirely on the round trip.
Manual copy-paste works fine for a five-row table pasted into a Markdown editor. Past that, you're hand-typing the delimiter row and hand-escaping every pipe character, and it stops being faster than any automated option.
8. Reverse Workflow: How to Import Markdown Format to Excel
The traffic runs both ways often enough to matter. If you're wondering how to import Markdown format to Excel, or need a markdown to excel path for a table living in a README or an AI-generated response, there are three workable routes:
- Paste directly into Excel, then use Data → Text to Columns, choosing the pipe (
|) as the delimiter. This works well for a single, simple table. - Save the Markdown table as a
.csvby stripping the pipes and delimiter row in a text editor first, then open the CSV normally in Excel. - Use Paste Special → Text when pasting into an existing sheet, which prevents Excel from trying to auto-format the raw pipe characters as part of the cell content.
None of these round-trips perfectly if the original table used advanced Markdown features (nested formatting, footnotes), but for a standard GFM pipe table, all three get clean rows and columns into a spreadsheet in under a minute.
9. Real-World Use Cases: Who Needs Excel to Markdown?
- Financial and data analysts paste quarterly metrics into a GitHub pull request, a Jira ticket, or a Confluence page, and a Markdown table reviews line-by-line in a diff the way a screenshot never could.
- Technical writers maintain a pricing or feature comparison matrix in a spreadsheet, because that's where stakeholders actually edit it, then publish it into a docs-as-code site without manually retyping every row.
- AI and RAG engineers flatten tabular source data into Markdown so an embedding model or an LLM's context window reads a clean table instead of choking on an unparsed binary attachment. A well-structured Markdown table is dramatically more token-efficient and legible to a model than a serialized
.xlsxblob.
10. Frequently Asked Questions
How do I convert Excel to Markdown without uploading files to a server?
Use a converter that runs entirely in the browser via JavaScript and the File API, rather than one that submits your file through a form. Check the browser's Network tab while converting — if no request carries your file, nothing was uploaded, regardless of what the tool's marketing copy claims.
Why do my dates turn into 5-digit numbers (like 46265) when converted to Markdown?
Excel stores dates as a serial number of days since 1900, with the "this should look like a date" instruction held separately in a style table. A converter that reads only the raw value and skips the style table will output the serial number instead of a readable date. The fix is using a converter (or a read_excel configuration) that resolves number formatting before writing output.
What happens to formulas in Excel when converting to Markdown tables?
The formula's cached result gets exported, not the formula text itself, since Markdown has no way to represent a live calculation. If a formula cell has no cached value, usually because it was written by a library rather than Excel itself, that cell exports blank. Re-saving the file in Excel populates the missing cache.
Can Markdown tables support merged cells (colspan / rowspan) from Excel?
No. GFM has no equivalent of colspan or rowspan. The standard convention keeps the value in the top-left cell of the merged range and leaves the rest of that range's cells empty in the output table.
How do I handle multi-tab workbooks when converting to Markdown?
Each worksheet should become its own ## Sheet Name section in the output, in the same order as the workbook, rather than converting only the active tab. This is the difference between a converter that's safe for real workbooks and one that quietly drops four out of five tabs.
How can I convert a Markdown table back to Excel?
Paste the table into Excel and use Data → Text to Columns with the pipe character as the delimiter, or strip the Markdown syntax and save the content as a .csv before opening it. Paste Special → Text also works for inserting a Markdown table into an existing sheet without formatting artifacts.
11. Conclusion & Next Steps
Getting from Excel to Markdown correctly means solving two separate problems: preserving the data faithfully (real dates, right-aligned numbers, every sheet, escaped pipes) and not creating a new copy of sensitive data on someone else's server to do it. A script that handles one without the other isn't really done.
If you have a spreadsheet to convert right now, drop it into the browser-based Excel to Markdown tool — it takes about as long to run as it took to read this sentence, and you can confirm the zero-upload claim yourself in DevTools before you trust it with anything sensitive. For everything else that needs to become Markdown, the same suite of 16 private file converters handles DOCX, PDF, CSV, and HTML the same way.